A pattern model answers a joint question: can the whole feature domain decode the task, and where is that information expressed? It fits one low-rank forward model
and then reuses that fit for classification or multivariate decoding, encoding, forward patterns, and restricted regional prediction. You do not fit one model to predict labels and another to draw a map.
This is the first of three pattern-model articles. Confirmation of a
frozen fit is vignette("Pattern_Confirmation"); pooling
confirmed subject loadings is
vignette("Pattern_Group").
When to use it
Use pattern_model() when you want one
covariance-aware fit over a whole domain (or a large ROI) and
several derived answers from it:
- held-out classification or multi-response decoding
- model-implied forward patterns, not only decoding weights
- how much of the whole-domain prediction remains accessible inside a region
- later confirmation or group analysis of those patterns
Use a different family when the question is narrower:
| Question | Model family |
|---|---|
| Decode feature vectors inside independently fitted regions |
feature_rsa_model
(vignette("Feature_RSA")) |
| Voxelwise encoding from grouped predictors |
banded_ridge_model
(vignette("Banded_Ridge_Encoding")) |
| Map between perception and retrieval domains |
remap_rrr_model
(vignette("REMAP_RRR")) |
| Find locally predictive neighborhoods with separate local fits | searchlight analysis
(vignette("Searchlight_Analysis")) |
The current residual covariance is diagonal plus a few shared noise components. It can miss richer local noise correlations. Spatial penalties act on the forward patterns , not on decoding weights.
What you pass in and get back
| Object | Role |
|---|---|
mvpa_dataset |
Brain measurements. Rows are observations; columns are features. |
design with model_targets()
|
Categorical labels (mvpa_design) or a numeric target
matrix (targets, feature_sets_design, or
feature_rsa_design). |
pattern_model() |
The specification: rank, noise, optional spatial penalty, optional observation weights. |
run_global() |
One domain-wide evaluation. Same specification also works with
run_regional() and run_searchlight(). |
pattern_global_result |
Held-out performance_table, prediction ledger, optional
fold fits, optional full-data refit. |
The usual next calls on that result are performance(),
model_importance() / model_patterns() on
$refit, local_performance(), and
predict() on a retained pattern_fit.
Plant four territories
The example has 120 observations in three runs and 48 voxels. Class
labels cycle through a, b, and c.
Four contiguous territories are planted:
- signal 1 (voxels 1–12): an A-versus-B code, plus a shared noise process
- signal 2 (voxels 13–24): a B-versus-C code
- shared noise (voxels 25–36): the same noise process, no task loading
- background (voxels 37–48): independent noise only
The shared-noise territory is a noise canceller. Observing it can improve whole-domain decoding even when its forward loading is near zero. That is why the guide keeps forward patterns and decoding weights as separate outputs.
n <- 120
p <- 48
class <- factor(rep(c("a", "b", "c"), length.out = n))
run <- rep(1:3, each = 40)
code <- model.matrix(~ class - 1)
X <- matrix(rnorm(n * p), n, p)
shared_noise <- rnorm(n, sd = 2)
X[, 1:12]  <- X[, 1:12]  + 1.2 * (code[, 1] - code[, 2]) + shared_noise
X[, 13:24] <- X[, 13:24] + 1.2 * (code[, 2] - code[, 3])
X[, 25:36] <- X[, 25:36] + shared_noise

space <- neuroim2::NeuroSpace(c(4, 4, 3), c(1, 1, 1))
mask <- neuroim2::NeuroVol(array(1, c(4, 4, 3)), space)
images <- neuroim2::NeuroVec(
  array(t(X), c(4, 4, 3, n)),
  neuroim2::NeuroSpace(c(4, 4, 3, n), c(1, 1, 1))
)
dataset <- mvpa_dataset(images, mask = mask)
design <- mvpa_design(data.frame(class, run), y_train = ~ class,
                      block_var = ~ run)
Fit the domain and score held-out runs
spec <- pattern_model(dataset, design, rank = 2,
                      noise = list(type = "diag_lowrank", rank = 1))
result <- run_global(spec, return_fits = TRUE, refit = TRUE)
performance(result)
#> # A tibble: 1 × 4
#>   Accuracy   AUC logloss rank_mean
#>      <dbl> <dbl>   <dbl>     <dbl>
#> 1    0.983 0.998  0.0532         2
performance() is leave-one-run-out accuracy. Chance is
one third. rank_mean is the mean rank selected across outer
folds; here rank is fixed at 2, so the column is exactly 2.
Two fits are retained for different jobs:
-
fold fits (
return_fits = TRUE) are the cross-validated estimators.local_performance()and the Haufe diagnostic need them. -
$refituses every training row. It is the descriptive map and the object you would confirm later. It is not the fit that produced the accuracy table.
return_fits = TRUE costs memory, especially with many
resamples.
X_all <- get_feature_matrix(dataset)
head(predict(result$refit, X_all, type = "prob"))
#>                 a            b            c
#> [1,] 9.965573e-01 7.158840e-14 3.442679e-03
#> [2,] 4.620917e-13 1.000000e+00 1.289233e-16
#> [3,] 2.736966e-05 1.686358e-10 9.999726e-01
#> [4,] 9.999999e-01 6.327767e-12 1.367196e-07
#> [5,] 1.725962e-11 1.000000e+00 3.411714e-13
#> [6,] 4.256850e-05 2.393210e-18 9.999574e-01
predict() on a pattern_fit returns class
probabilities, class labels, decoded continuous targets, calibrated
scores, or encoded brain measurements. The probabilities above come from
the descriptive refit, so they are not the held-out scores in
performance().
Read where the signal lives
signal_sd <- model_importance(result$refit, type = "signal_sd")
information <- model_importance(result$refit, type = "conditional_info")
oldpar <- par(mfrow = c(1, 2), mar = c(4, 4, 2, 1))
for (panel in list(
  list(y = signal_sd, ylab = "Signal SD"),
  list(y = information, ylab = "Conditional information (nats)")
)) {
  plot(panel$y, type = "h", xlab = "Input voxel", ylab = panel$ylab)
  abline(v = c(12.5, 24.5, 36.5), lty = 2, col = "grey70")
  mtext(c("S1", "S2", "noise", "bg"), side = 3, line = 0,
        at = c(6, 18, 30, 42), cex = 0.8)
}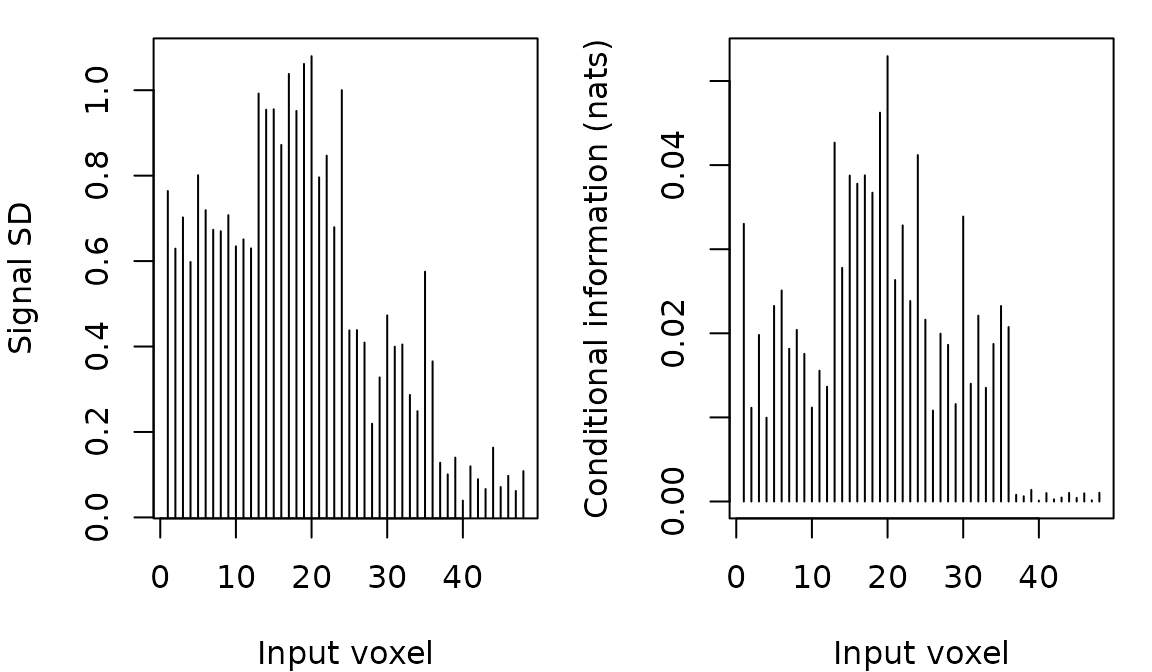
par(oldpar)Signal SD is in the original measurement units. It says where fitted task variance is expressed. In this realization the B-versus-C territory (S2) is strongest, the A-versus-B territory (S1) is next, and background is near zero. The shared-noise territory is not exactly zero: finite-sample loadings rarely vanish without a sparsity penalty.
Conditional information asks what a voxel adds once the other voxels have been observed. It can be high in a noise canceller whose signal SD is modest. It is a working Gaussian score-model quantity, in nats — not empirical mutual information about class labels, and not a significance map.
model_importance(result) builds a spatial image through
the dataset. model_importance(result$refit) returns a
vector aligned to input columns; screened columns are NA.
Component-wise forward patterns and calibrated decoder weights come from
model_patterns(fit, "forward") and
model_patterns(fit, "weights"). Those columns depend on the
chosen component coordinates. Scalar maps do not.
Ask what each region can decode
local_performance() keeps the whole-domain task
representation and restricts only the residual covariance to the region.
It then predicts the same held-out observations used
for the whole-domain score. Cropping whole-brain decoding weights would
keep noise-cancellation terms that require unobserved voxels; that is a
different, generally incorrect, estimand.
regions <- list(
  signal_1     = 1:12,
  signal_2     = 13:24,
  shared_noise = 25:36,
  background   = 37:48,
  whole_domain = 1:48
)
local <- local_performance(result, regions)
local[local$metric == "Accuracy", ]
#>          region   metric whole_brain local_restricted
#> 1      signal_1 Accuracy   0.9833333        0.3250000
#> 4      signal_2 Accuracy   0.9833333        0.9750000
#> 7  shared_noise Accuracy   0.9833333        0.3916667
#> 10   background Accuracy   0.9833333        0.2916667
#> 13 whole_domain Accuracy   0.9833333        0.9833333
Each name in regions is a set of input-matrix
column positions, not voxel IDs.
In this realization the table matches the planting:
- signal 2 decodes well on its own.
- signal 1 is near chance by itself. It carries both the A-versus-B code and the shared noise, and without the canceller it cannot separate them.
- shared noise is also near chance alone, as it should be: it has no task loading.
- whole domain recovers the high held-out accuracy. The canceller is useful only when the signal territories are observed with it.
The regional score is access under the shared whole-brain
representation, not the best accuracy a separately trained local model
could reach. A finite-sample region can beat the whole-domain number.
For a true independent-ROI comparison, pass fold-resolved ledgers
through independent_roi; those ledgers must match rows,
folds, truth, and baselines.
Decode continuous feature targets
The same constructor accepts a numeric target matrix. The example below encodes two continuous features into the first two territories.
features <- matrix(rnorm(n * 2), n, 2,
                   dimnames = list(NULL, c("feature_1", "feature_2")))
brain <- matrix(rnorm(n * p), n, p)
brain[, 1:12]  <- brain[, 1:12]  + features[, 1]
brain[, 13:24] <- brain[, 13:24] + features[, 2]
continuous_data <- mvpa_dataset(
  neuroim2::NeuroVec(
    array(t(brain), c(4, 4, 3, n)),
    neuroim2::NeuroSpace(c(4, 4, 3, n), c(1, 1, 1))
  ),
  mask = mask
)
continuous_design <- mvpa_design(
  data.frame(id = 1:n, run),
  cv_labels = 1:n, targets = features, block_var = ~ run
)
continuous <- run_global(
  pattern_model(continuous_data, continuous_design, rank = 2),
  return_fits = TRUE
)
performance(continuous)
#> # A tibble: 1 × 4
#>      R2  RMSE   cor rank_mean
#>   <dbl> <dbl> <dbl>     <dbl>
#> 1 0.903 0.304 0.950         2
local_performance(continuous, list(first = 1:12, second = 13:24))
#>   region metric whole_brain local_restricted
#> 1  first     R2   0.9030424        0.4457892
#> 2  first   RMSE   0.3038478        0.6301593
#> 3  first    cor   0.9503506        0.5334221
#> 4 second     R2   0.9030424        0.3383942
#> 5 second   RMSE   0.3038478        0.7056156
#> 6 second    cor   0.9503506        0.4523845
R2 is predictive R-squared against each fold’s
training-target mean, not squared correlation, and it
can be negative. The reported value averages per-response R-squared.
Targets are centred and whitened on training rows only;
predict(..., type = "decode") returns original target
units. Here each territory reconstructs its own feature only partly; the
whole domain does much better because both features are observed
together.
feature_sets_design is the other common
continuous-target path. Its row_weights are used by the
estimator (see below).
Control rank, penalties, and weights
Rank. "auto" (the default) selects rank
inside each outer training split by held-out decoding loss, then reports
rank_mean. A fixed integer is used as given and still
capped at the eligible rank (number of classes minus one for categorical
targets).
Spatial penalties act on . They are optional and they are hypotheses about anatomy, not defaults.
# Localized support: a feature is in the patterns or out of them.
pattern_model(dataset, design, rank = 2, penalty = list(sparse = 0.1))

# Neighbouring voxels should carry similar signed loadings.
# A spatial_graph() is built from the dataset when one is not supplied.
pattern_model(dataset, design, rank = 2, penalty = list(signed_smooth = 1))
sparse is a fraction of the penalty that empties the
model, so 0.1 means the same thing across folds and
domains. signed_smooth is the weight of a graph-Laplacian
term relative to the data-fit curvature. Either entry may be
"auto", which cross-validates a short path jointly with
rank. Do not default to sparse = "auto" on
a dense or weak whole-brain code: inner folds can pick a penalty that
hurts held-out accuracy. Use sparsity when you believe support is
localized. support_smooth is reserved for a later envelope
penalty and is rejected rather than quietly remapped.
Observation weights enter the fit itself: centring, target whitening, the residual covariance, the objective, and the inner tuning loss. They do not reweight the reported metrics — every tested observation still counts once.
# Explicit weights override design-carried row_weights.
# A zero weight drops that row from training, exactly.
pattern_model(dataset, design, rank = 2, weights = w)
If the design is a feature_sets_design, its
row_weights are used automatically. Integer weights are
equivalent to replicating rows. Confirmation
(vignette("Pattern_Confirmation")) does not accept
nonuniform weights.
Rotate a display and compare folds
view <- rotate_patterns(result$refit)
view$reconstruction_error
#> [1] 1.272449e-15
result$component_stability[, c("fold1", "fold2", "rank1", "rank2",
                               "n_common", "overlap")]
#>   fold1 fold2 rank1 rank2 n_common   overlap
#> 1     1     2     2     2       48 0.9213209
#> 2     1     3     2     2       48 0.8117325
#> 3     2     3     2     2       48 0.7999901
rotate_patterns() changes display coordinates while
preserving
.
The underlying fit is unchanged, so predictions and scalar maps stay
bit-identical. Only orthogonal rotations are supported. Compare patterns
across folds or subjects with the column space, the support, or a
coordinate-invariant map — never raw entries of
.
component_stability compares spatial column spaces with
principal angles on features retained in both folds. An overlap of one
means the two nonempty subspaces coincide. Unequal ranks reduce overlap
even if the smaller space sits inside the larger. This is a subspace
diagnostic, not a test that a particular rank is supported.
vapply(result$haufe_diagnostics, function(x) x$relative_discrepancy,
       numeric(1))
#> [1] 0.4278746 0.5853670 0.7012616
The Haufe diagnostic compares empirical held-out covariance patterns
with the model-implied patterns. Large discrepancies can flag sampling
noise or misspecification; they are not p-values. Automatic
results use train:<row ID> for training and CV rows
and test:<row ID> for an external test partition.
Independence of an external partition is a caller obligation. For a
separately held-out matrix, call
pattern_haufe(fit, X_holdout, observation_ids).
Save and continue
save_results(result, "pattern-output")The RDS stores the result, including retained fits and ledgers. Spatial refit maps are also written as images for supported datasets. Multibasis image aggregation is refused because averaging channels would change the estimand; those results save as RDS.
To test the frozen discovery directions on new rows, continue with
vignette("Pattern_Confirmation"). To pool confirmed subject
loadings in a shared target basis, use
vignette("Pattern_Group").